Key takeaways
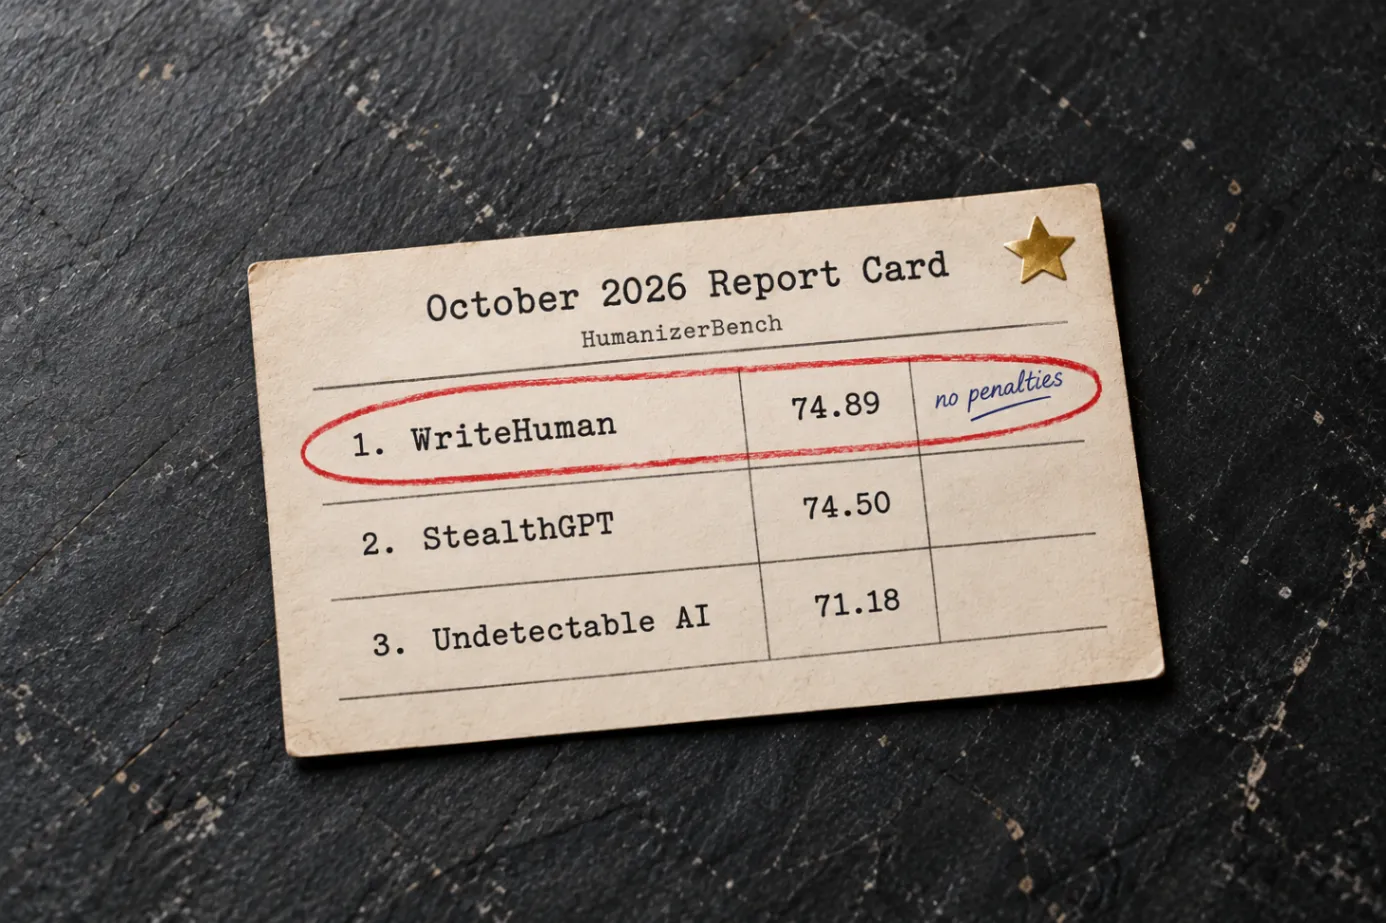
- WriteHuman finished #1 of 14 tools in the October 2026 AI humanizer rankings with a composite score of 74.89, its fourth straight cycle on top.
- The test got harder: Pangram 4 joined as a sixth detector, and each rewrite is now scored on the average of all six detector verdicts instead of the median.
- WriteHuman posted the top score in the field on GPTZero (99.5%), Winston AI (100.0%) and Originality.ai (100.0%).
- Ten of the 14 tools were penalized for meaning drift or length inflation. WriteHuman took no penalties and was the highest ranked of the four clean tools.
- Of September's top five, WriteHuman is the only tool still in the top five after the methodology update.
- Every WriteHuman result came from Basic, its entry-level paid plan.
WriteHuman is the #1 AI humanizer in the October 2026 HumanizerBench rankings, finishing first of 14 tools with a composite score of 74.89. That makes four cycles in a row at the top of the board: July, August, September, and now October. It also came on the toughest version of the test so far.
If you are new to this series, HumanizerBench is a public monthly benchmark that our team built and runs. Every tool, WriteHuman included, rewrites the same 30 AI-written samples, every rewrite is checked by a panel of AI detectors, and the same scoring rules apply to us as to everyone else. The prompts, outputs, detector verdicts and scoring script for every cycle are published on GitHub, so anyone can rerun the numbers.
The test got harder this month
October brought three methodology changes at once, and the first two raise the bar for every tool on the board.
A sixth detector. Pangram joined the panel, running its newest model, Pangram 4. It scores the share of a text it rates as human-written, so anything it reads as AI-assisted counts against the tool.
Every detector now counts. Until this cycle, each rewrite's detector score was the median of the panel's verdicts. With six detectors, a median only reflects the middle two, so a tool could be caught outright by two detectors and still score close to 100%. From October, the score is the average of all six verdicts. To post a high detector pass rate, a tool has to get past every detector on the panel, not just most of them.
Newer source texts. The AI-written samples now come from GPT-6 Sol, Gemini 3.8 Flash and Claude Sonnet 5.5, the newest model from each of the three labs.
The composite weights and penalty rules did not change. Because detector results are now scored differently, though, October scores are not comparable with earlier cycles, and the board looks very different. Of September's top five, WriteHuman is the only one still there. The other four finished sixth, eighth, ninth and eleventh.
How the October board finished
Here is the top five.
Rank | Tool | Score | Detector pass rate | Penalties |
|---|---|---|---|---|
1 | WriteHuman | 74.89 | 88.8% | None |
2 | StealthGPT | 74.50 | 88.1% | -3 |
3 | Undetectable AI | 71.18 | 74.6% | -5 |
4 | Clever AI Humanizer | 69.02 | 80.1% | -4 |
5 | Humanize AI Pro | 68.87 | 63.4% | -1 |
WriteHuman posted the highest detector pass rate in the top five at 88.8%, and it was the only top-five tool to finish without a penalty. The other four all had points taken off their composite scores for quality problems before the final standings were set.
Top score on GPTZero, Winston AI and Originality.ai
On three of the six detectors, WriteHuman posted the highest score of any tool in the field.
Detector | WriteHuman score | Rank in the field |
|---|---|---|
GPTZero | 99.5% | 1st of 14 |
Winston AI | 100.0% | 1st of 14 |
Originality.ai | 100.0% | 1st of 14 |
Each of those is an average across all 30 rewrites, scored with each detector's newest model, and no other humanizer matched WriteHuman on any of the three.
Ten tools took penalties. WriteHuman took none.
HumanizerBench does not only check whether text gets past detectors. It also takes points off when a tool gets there the wrong way. A rewrite is flagged for meaning drift when it strays too far from what the original said, and for length inflation when it comes back more than 40% longer than the text it was given.
This cycle, 10 of the 14 tools were penalized for one or both. WriteHuman had no meaning drift flags and no length inflation flags on any of its 30 rewrites. Only four tools finished with a clean score, and WriteHuman was the highest ranked of them.
We think this is the most important column on the board, because it catches what a detector cannot see: a rewrite that changes your point or buries it in filler. A rewrite that clears a detector that way has not done the job. WriteHuman's penalty column is empty for the second month running.
Around the rest of the board
StealthGPT made the biggest climb of the cycle, from ninth in September to second. It took three penalty points for meaning drift along the way, while WriteHuman took none. If you are weighing the two, our StealthGPT comparison lays out the head-to-head.
Stealth Writer, September's runner-up, fell from second to eighth and picked up three penalty points. Our Stealth Writer comparison has the details.
Clever AI Humanizer is new to the benchmark this month and debuted in fourth place, with four penalty points for meaning drift.
Humbot returned to the benchmark and finished 13th. Nineteen of its 30 rewrites came back more than 40% longer than the text it was given, enough to hit the 10-point cap on the length inflation penalty.
Phrasly finished 12th after losing 11 penalty points, nine of them for meaning drift.
Tested on the Basic plan
WriteHuman was tested on Basic, its entry-level paid plan and the same plan anyone can sign up for today. The first-place finish and the top marks on GPTZero, Winston AI and Originality.ai all came from Basic, not a premium tier. Plan details are published alongside the results on humanizerbench.com.
The full October standings
Rank | Tool | Score | Penalty |
|---|---|---|---|
1 | WriteHuman | 74.89 | None |
2 | StealthGPT | 74.50 | -3 |
3 | Undetectable AI | 71.18 | -5 |
4 | Clever AI Humanizer | 69.02 | -4 |
5 | Humanize AI Pro | 68.87 | -1 |
6 | AI Humanize io | 68.24 | None |
7 | Super Humanizer | 67.58 | -1 |
8 | Stealth Writer | 65.98 | -3 |
9 | HIX Bypass | 65.14 | None |
10 | Walter Writes | 63.53 | -9 |
11 | SupWriter | 62.75 | None |
12 | Phrasly | 61.79 | -11 |
13 | Humbot | 61.74 | -10 |
14 | Grammarly | 61.29 | -3 |
For anyone who wants the formula, the composite score weighs detector results at 42%, meaning preservation at 32%, readability at 16% and consistency at 10%, with penalty points subtracted after that. The full methodology, every sample and every detector verdict are public at humanizerbench.com.
Four in a row, and November is next
Four straight cycles at #1, the latest on the hardest test yet, is exactly the result we were working toward. The November cycle runs next month, and the results will be posted here as soon as they are in.
In the meantime, the best test is still your own. Take something you drafted with AI, run it through WriteHuman, and check the output with our AI detector or whichever one you trust. Then read it out loud and see if it still sounds like you.
Frequently asked questions
Sources (2)
- 1.HumanizerBench October 2026 leaderboardhumanizerbench.com
- 2.